Cross-platform local pdf resume editing using Mozilla-inspired tools
If you have grandkids who use you as an emergency tech wizard, you'll understand that they have the strangest of "emergencies" we need to fix.
An hour ago, I got an "emergency" call from a recent high school graduate who needed her GoogleDocs-to-PDF resume reduced to 2 pages because a job application with a deadline of midnight tonight wouldn't take 3 pages.
Having retired more than 15 years ago, I can't even spell resume anymore, but an "emergency" is an emergency, after all, so here's what happened.
Note: I did not have the luxury of time to figure out a "better way", so
the intent of this Usenet thread is half to edify the team and half to see if the team knows of a better way for a kid to edit/convert PDF resumes.
Given it's a resume, I only briefly considered online conversion tools, but decided against them since it's rude to put contact information on the net.
It had to be a cross-platform local solution 'cuz she's on the Apple platform, and I'm on Windows, so whatever I did she had to be able to do.
Here's what I did.
1. She emailed me her 3-page PDF which I converted to HTML with Calibre.
<https://calibre-ebook.com/>
2. That converted the 3-page PDF to HTML, RTF, MSWord, TEXT, EPUB, etc.
3. I tried editing/printing/saving in Mozilla Firefox, but couldn't edit.
4. I then tried the Mozilla-derived SeaMonkey Composer & that worked.
5. So I didn't go any further as time was of the essence.
But SeaMonkey Composer is an HTML editor, not a PDF editor.
See below for my installation log notes I hurriedly wrote on the fly
and sent to her after I used the process below to convert 3 pages to 2. ===============
Apparently the Mozilla-derived SeaMonkey Composer is a good choice
for editing a single, relatively simple HTML resume because the
SeaMonkey "Composer" tool is an easy-to-use FOSS WYSIWYG editor.
<https://www.seamonkey-project.org/releases/>
1. Open the existing HTML resume file
2. Make changes to text, formatting, links, tables and images
without having to work directly with HTML tags.
3. Be careful as there is no warning when overwriting html files!
(obviously that means only edit backups)
SeaMonkey Composer is free, ad free, registration free and open source. SeaMonkey Composer Works on all desktop platforms (macOS/Linux/Windows).
Its main limitation is its age as it isn't well suited to modern CSS.
But for a simple 2-page resume, that should not be a major issue. ===============
Warning: Phones home on first invocation (so use your network killswitch).
Note: My paths are shown below. Use whatever paths make sense to you.
Always hit the network killswitch whenever installing any software.
A. mkdir C:\software\editor\htm\seamonkey
B. <https://www.seamonkey-project.org/releases/>
<https://www.seamonkey-project.org/releases/seamonkey2.53.24/>
<https://www.seamonkey-project.org/releases/>
<https://archive.seamonkey-project.org/releases/2.53.24/win64/en-GB/seamonkey-2.53.24.en-GB.win64.installer.exe>
Name: seamonkey-2.53.24.en-US.win64.installer.exe
Size: 49055000 bytes (46 MiB)
SHA256: 53B8685984F6115AB6251FD7061335D5CF58C2199E97F54EE3D0857BFFDDF9D7
C. Choose "Custom" install into C:\app\editor\htm\seamonkey
D. Copy resulting desktop shortcut to C:\menu\editor\htm\seamonkey
Target: C:\app\editor\htm\seamonkey\seamonkey.exe
===============
1. Start SeaMonkey
2. Edit > Preferences (check settings and set as desired)
(e.g., history, downloads, auto-updates, clear private data, etc.)
3. Since we're dealing with HTML, decide what to set for
Edit > Preferences > Composer
When Saving or Publishing Pages (below are the defaults)
[_]Preserve original source formatting
[X]Save images and other associated files when saving pages
[_]Always show Publish dialog when publishing pages
Editing
[X]Maintain table layout when inserting or deleting cells
[_]Use CSS styles instead of HTML elements and attributes
[_]Return in a paragraph always creates a new paragraph
===============
History of SeaMonkey (which is independent from Mozilla at this time)
a. Apparently, Netscape went open source in 1998
b. The Mozilla all-in-one suite apparently started with that code
c. Firefox (web) & Thunderbird (email) split off around 2003/2004
d. A group of community developers took on the Mozilla code base
<https://www.reddit.com/r/firefox/comments/1wltcqf/does_seamonkey_i_like_the_ui_have_any_affiliation/>
e. The result was "SeaMonkey" <https://www.seamonkey-project.org/> ===============
Make a copy of your html resume (as SeaMonkey Composer doesn't warn on save)
1. Start SeaMonkey and go to Window > Composer
2. Open the resume using File > Open File > resume.html
3. Edit as desired & File > Save when done
===============
After the "emergency" was over, I looked for "better" x-platform solutions.
<https://www.pdfgear.com/pdf-editor-reader/open-source-pdf-editors.htm>
According to that article, these are 7 open source X-platform PDF editors:
1. LibreOffice <https://www.libreoffice.org/>
2. Inkscape <https://inkscape.org/>
3. PDFSam <https://pdfsam.org/>
4. OpenOffice <https://www.openoffice.org/product/draw.html>
5. PDFedit <http://pdfedit.cz/en/index.html>
6. Scribus <https://www.scribus.net/>
And, if we ignore Linux & Windows...
6. Preview <https://support.apple.com/guide/preview/welcome/mac>
Interestingly, SeaMonkey wasn't on the list. I'm not sure why not.
Neither was Stirling Desktop on the list, so I'd be curious if
anyone has experience with their "free" proprietary PDF editor?
mkdir C:\software\editor\pdf\stirling
<https://www.stirling.com/download> (mac/windows/linux)
<https://files.stirlingpdf.com/win-installer.exe>
Name: seamonkey-2.53.24.en-US.win64.installer.exe
Size: 49055000 bytes (46 MiB)
SHA256: 53B8685984F6115AB6251FD7061335D5CF58C2199E97F54EE3D0857BFFDDF9D7
Always hit the network killswitch whenever installing any software.
Install into C:\app\editor\pdf\stirling
Move the desktop shortcut into C:\menu\editor\pdf\stirling.lnk
When it starts up, click "Continue without signing in".
Click "Open Files" & then "PDF Editor" to edit the PDF file.
In summary, the "emergency" was I was afforded only an hour to edit
a Google-Docs-created PDF from 3 pages to 2 pages, where my install
log is above, and I now ask the desktop PDF editing community ...
Q: What do you use for quick PDF editing of sensitive documents?
A: ?
It had to be a cross-platform local solution 'cuz she's on the Apple platform, and I'm on Windows, so whatever I did she had to be able
to do.
who needed her GoogleDocs-to-PDF resume reduced to 2 pages because a job >application with a deadline of midnight tonight wouldn't take 3 pages.
Q: What do you use for quick PDF editing of sensitive documents?
A: ?
who needed her GoogleDocs-to-PDF resume reduced to 2 pages because a job >application with a deadline of midnight tonight wouldn't take 3 pages.
Q: What do you use for quick PDF editing of sensitive documents?
A: ?
Cross-platform local pdf resume editing using Mozilla-inspired tools
If you have grandkids who use you as an emergency tech wizard, you'll understand that they have the strangest of "emergencies" we need to fix.
An hour ago, I got an "emergency" call from a recent high school graduate
who needed her GoogleDocs-to-PDF resume reduced to 2 pages because a job application with a deadline of midnight tonight wouldn't take 3 pages.
Having retired more than 15 years ago, I can't even spell resume anymore,
but an "emergency" is an emergency, after all, so here's what happened.
Note: I did not have the luxury of time to figure out a "better way", so
the intent of this Usenet thread is half to edify the team and half to see
if the team knows of a better way for a kid to edit/convert PDF resumes.
Given it's a resume, I only briefly considered online conversion tools, but decided against them since it's rude to put contact information on the net.
It had to be a cross-platform local solution 'cuz she's on the Apple platform, and I'm on Windows, so whatever I did she had to be able to do.
Here's what I did.
1. She emailed me her 3-page PDF which I converted to HTML with Calibre.
<https://calibre-ebook.com/>
Q: What do you use for quick PDF editing of sensitive documents?
A: ?
I truly can not understand. My resum|- was a .doc file, not .pdf. That
is, I had the source file, which I then converted to pdf and sent that
to people. But I owned the doc, or rather, the staroffice or libre
office equivalent at the time.
On 11/11/2026 13:32, Carlos E.R. wrote:
I truly can not understand. My resum|- was a .doc file, not .pdf. That
is, I had the source file, which I then converted to pdf and sent that
to people. But I owned the doc, or rather, the staroffice or libre
office equivalent at the time.
I use Markdown + Pandoc :-D.
https://github.com/john-bokma/resume-pandoc
I use Markdown + Pandoc
On 2026-11-11 16:19, John Bokma wrote:
On 11/11/2026 13:32, Carlos E.R. wrote:
I truly can not understand. My resumo was a .doc file, not .pdf. That
is, I had the source file, which I then converted to pdf and sent that
to people. But I owned the doc, or rather, the staroffice or libre
office equivalent at the time.
I use Markdown + Pandoc :-D.
https://github.com/john-bokma/resume-pandoc
My first resumo was in Wordperfect 5.1 for MsDOS. I had not even heard
of latex or markdown. Had never touched *nix.
On Wed, 11 Nov 2026 16:19:42 +0100, John Bokma wrote:
I use Markdown + Pandoc
Great combination. I added the ability to format a text field as
Markdown via Pandoc to a project for a client recently. Only trouble
was, when the browser shows the PDF version, it insists on displaying
a list of thumbnails down the side, because that's what the settings
in the PDF file say to do.
Turning this off involved massaging the generated PDF data with
PikePDF. But the project was in PHP (no, I didn't start it, I just
took it over), and I couldn't find any PHP binding for PikePDF. So I
wrote a little Python script to do the postprocessing (and the
Markdown rendering, while it was at it).
Yes, it was an excuse to introduce some Python code into a
predominantly-PHP project
Carlos E.R. wrote:
On 2026-11-11 16:19, John Bokma wrote:
On 11/11/2026 13:32, Carlos E.R. wrote:
I truly can not understand. My resumN++ was a .doc file, not .pdf. That >>>> is, I had the source file, which I then converted to pdf and sent that >>>> to people. But I owned the doc, or rather, the staroffice or libre
office equivalent at the time.
I use Markdown + Pandoc :-D.
https://github.com/john-bokma/resume-pandoc
My first resumN++ was in Wordperfect 5.1 for MsDOS. I had not even heard
of latex or markdown. Had never touched *nix.
Paul understood that it was a Google-doc-to-pdf, which, I guess, is what
kids use 'cuz likely they are taught that in high school for all I know.
What format is a "google-doc" in?
Hell if I know. I've never used google docs.
I don't even know what it is.
But when I asked her for the original, I assumed it would be MS Word.
But it wasn't. And she only had the PDF.
So, kids being kids, it was what it was.
Anyway, I could easily convert, with the FOSS Calibre, to RTF/DOCX.
But my MS word from 2010 isn't working 'cuz I accidentally cleaned it up.
So I could convert to MS Word, but I couldn't edit it.
And remember, I only had an hour at most.
It was all done while we were on the phone call.
Because it was an "emergency", you know. Kids. You know.
Anyway, I was actually shocked that the Mozilla-derived SeaMonkey Composer solved the problem WITHOUT me doing anything. Seriouslly. I was shocked.
I loaded the 3-page Google-docs-to-PDF-to-HTML-via-Calibre into
SeaMonkey Composer and, voila, instantly, it was already only 2 pages.
I saved it, and then when I tried to compare with the original HTML,
that's when I realized it overwrote the original, which SeaMonkey Composer should have warned us about.
At that point, I printed it to PDF from inside SeaMonkey Composer, and checked that the PDF was 2 pages (and fixed a couple of typos).
Cross-platform local pdf resume editing using Mozilla-inspired tools
pdfcraft. It has a portable version as well. Just download a zip file,
unzip it and start using it.
<https://getartcraft.com/apps/pdfcraft>
Q: What do you use for quick PDF editing of sensitive documents?
A: ?
To remove a page from a PDF file I think I would use Gimp, something
like this:
-Use Gimp to import the PDF as layers.
-Click the "eyes" in the layers display to remove the page you
don't want. Use 600 dpi.
-Export as .mng to file.mng. That is a multi-page format that can
be converted to a PDF.
-Convert the file.mng to file.pdf like this:
convert -density 600 file.mng file.pdf
On Thu, 12 Nov 2026 05:23:52 -0000 (UTC), Joseph Rosevear wrote:
To remove a page from a PDF file I think I would use Gimp, something
like this:
-Use Gimp to import the PDF as layers.
-Click the "eyes" in the layers display to remove the page you
don't want. Use 600 dpi.
-Export as .mng to file.mng. That is a multi-page format that can
be converted to a PDF.
-Convert the file.mng to file.pdf like this:
convert -density 600 file.mng file.pdf
ThatrCOs not only complicated, fiddly and time-consuming, itrCOs also
going to lose quality.
On Wed, 11 Nov 2026 16:19:42 +0100, John Bokma wrote:
I use Markdown + Pandoc
Great combination. I added the ability to format a text field as
Markdown via Pandoc to a project for a client recently. Only trouble
was, when the browser shows the PDF version, it insists on displaying
a list of thumbnails down the side, because thatrCOs what the settings
in the PDF file say to do.
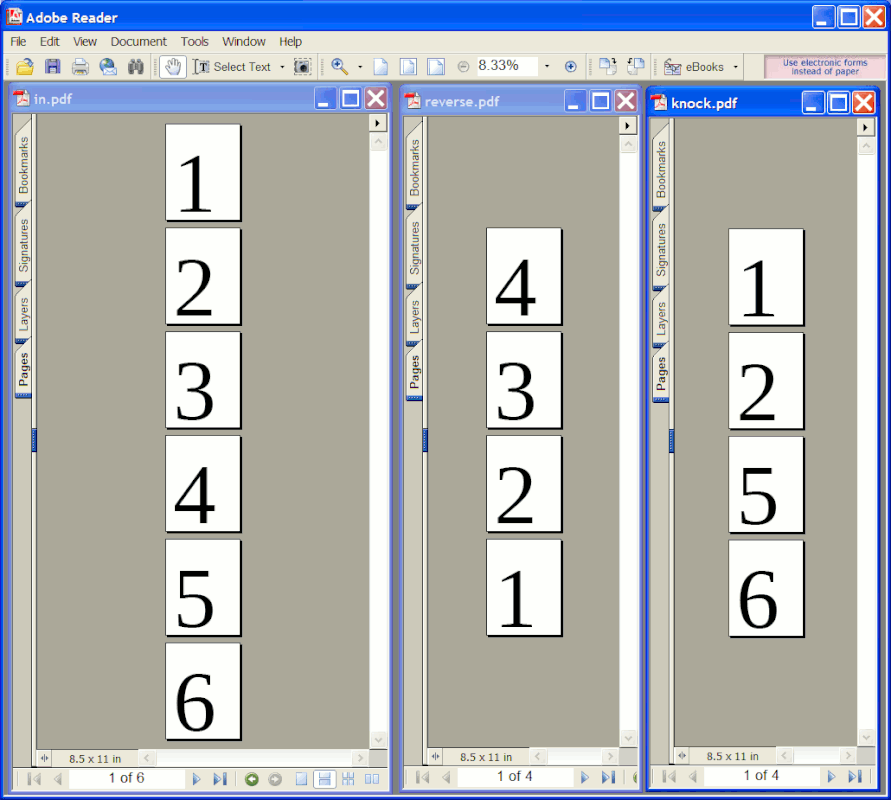
mutool merge -o reverse.pdf in.pdf 4 in.pdf 3 in.pdf 2 in.pdf 1
I just tried to create an empty document, and google suggested several templates, one of them a resumo. I clicked on that. Once there, you can download it, as doc, as odt, as pdf. Even epub and markdown. Problem
solved. :-)
At that point, I printed it to PDF from inside SeaMonkey Composer, and
checked that the PDF was 2 pages (and fixed a couple of typos).
I told you recently that Firefox is attempting to create the best PDF
reader out there. :-)
On 11/11/2026 20:46, Lawrence DrCOOliveiro wrote:
Only trouble was, when the browser shows the PDF version, it
insists on displaying a list of thumbnails down the side, because
thatrCOs what the settings in the PDF file say to do.
According to Claude:
---
header-includes:
- \hypersetup{pdfpagemode=UseNone}
---
or
pandoc input.md -o output.pdf -V \
header-includes="\hypersetup{pdfpagemode=UseNone}"
Haven't tried it out yet.
Free PDF Editor:
<https://www.getfreepdf.com/en/>
As I do not have access to Microsoft-< systems, I cannot tell you
what this software does, but on the page it sais: -----------------------------------
The free PDF editor alternative to Adobe Acrobat for business and personal use
Your PDF solution: View, create and edit PDFs rCo
quickly, easily and free of charge
-----------------------------------
I can tell you though, that this is German software, I have been
there and had two job interviews in the company. Usually their
software is cool, but I do not like the interaction with the
Internet and less the integration of AI agents in the commercial
tools.
Cheerio
Free PDF Editor:Too bad its only for Windows, whereas they offer for Linux
<https://www.getfreepdf.com/en/>
As I do not have access to Microsoft-< systems, I cannot tell you
what this software does, but on the page it sais: >-----------------------------------
The free PDF editor alternative to Adobe Acrobat for business and personal use
Your PDF solution: View, create and edit PDFs rCo
quickly, easily and free of charge
-----------------------------------
I can tell you though, that this is German software,Indeed it is. The "About us" names Nuremberg as home town. But they
Generally, when it comes to text editing, there is neverThis remembers me of beloved old TSO/ISPF https://hunterstrainingassociates.com/ISPF_Tutorial/ISPF_Tutor_two.htm
a description of "flowed text". Most of the editors do this.
+----------------------------+
| The quick brown fox jumped | <=== Each line is edited stand alone
+----------------------------+
| over the lazy hen, which |
+----------------------------+
| laid a scrambled egg. |
+----------------------------+
<https://www.getfreepdf.com/en/>Too bad its only for Windows,
Generally, when it comes to text editing, there is never
a description of "flowed text". Most of the editors do this.
+----------------------------+
| The quick brown fox jumped | <=== Each line is edited stand alone
+----------------------------+
| over the lazy hen, which |
+----------------------------+
| laid a scrambled egg. |
+----------------------------+
This remembers me of beloved old TSO/ISPF https://hunterstrainingassociates.com/ISPF_Tutorial/ISPF_Tutor_two.htm
that helped me to stagger about the terminal's screen :-).
That was, what I later learned, a line-oriented editor.
Wheras this is great for writing programs, one wouldn't want to write
a love-letter with it. Thank heavens, even the most basic editor in my
linux is text-oriented. If I do not disturb it by introducing
line-feeds myself.
a. Start with a PDF of unknown flowing format
b. Convert to free-flowing format (e.g., epub)
c. Then re-export the epub to PDF
k2pdfopt apparently detects text columns geometrically and re-typesets them to a target width such that source line endings stop mattering entirely.
k2pdfopt -w 600 -h 900 -mode fw -wrap- -n -y input.pdf -o output.pdf
It discards the original glyph positions & re-wraps from the text itself.
-mode fw fits to a single narrow column
-wrap- forces its own reflow rather than the PDF's native wrap
-w/-h are the screen in pixels
Add -col 2 for two-column sources
And, there's a -gui mode that previews page by page, if desired
If the text was actually handled flowed, you could resize the outer bounding box and the tool would handle the details. The internal representation inside the PDF is not flowed, and the reason the first editing capability exists,
is it closely matches how the text is stored in the PDF. Whereas to do this, requires a good deal of cleverness and luck. This is what the customers
think they are getting, when we talk of "editing".
Amazingly, it knew *instantly* a fake email address.
WTF? How?
Generally, when it comes to text editing, there is never a
description of "flowed text". Most of the editors do this.
+----------------------------+
| The quick brown fox jumped | <=== Each line is edited stand alone
+----------------------------+
| over the lazy hen, which |
+----------------------------+
| laid a scrambled egg. |
+----------------------------+
As we were forewarned, when I go to the site, it asks for 2 things
Name (optional)
Email (not optional)
Country (not optional)
<https://www.getfreepdf.com/en/download>
Amazingly, it knew*instantly* a fake email address.
WTF? How?
Generally, when it comes to text editing, there is never a
description of "flowed text". Most of the editors do this.
+----------------------------+
| The quick brown fox jumped | <=== Each line is edited stand alone
+----------------------------+
| over the lazy hen, which |
+----------------------------+
| laid a scrambled egg. |
+----------------------------+
PDFMiner has heuristics to deal with this. I used it to build a post-processor for extracting customer and addressing information from invoices generated by a customer's accounting/reporting system, for automatically mailing them out. Once I had accumulated a suitable
collection of test cases for tuning the extraction parameters, it all
worked quite nicely. ??
<https://github.com/pdfminer/pdfminer.six>
python -m venv venvCollecting pdfminer.six
venv\Scripts\activate
pip install pdfminer.six
curl -o resume.pdf https://cdn.uconnectlabs.com/wp-content/uploads/sites/123/2025/05/MITCAPD-PhDI.pdf% Total % Received % Xferd Average Speed Time Time Time Current
venv\Scripts\activate
type extracted_resume.txt--------------------- begin extracted resume ---------------------
Hmmm... I just realized, belatedly, that pdfminer.six was overkill for
*that* specific simple PDF file, but for a large complex multi-column
layout, I can see how Lawrence's suggested pdfminer.six can reconstruct
a logical reading order to give him/us a reliable way to pry data out.
What other tasks do you do to edit or modify a PDF file?
Usenet freeware PDF utility and toolchain reference chart.
Edit layout and content
LibreOffice, Inkscape, Scribus ...
On Sun, 15 Nov 2026 02:23:21 -0400, Maria Sophia wrote:
Usenet freeware PDF utility and toolchain reference chart.
Edit layout and content
LibreOffice, Inkscape, Scribus ...
Not freeware <https://en.wikipedia.org/wiki/Freeware>, but
Free software <https://en.wikipedia.org/wiki/Free_software>.
On Sat, 11/14/2026 3:55 AM, Michael Uplawski wrote:
Free PDF Editor:
<https://www.getfreepdf.com/en/>
Do you have a copy at the moment ?
Le Sat, 14 Nov 2026 04:30:36 -0500, Paul a |-crit-a:
On Sat, 11/14/2026 3:55 AM, Michael Uplawski wrote:
Free PDF Editor:
<https://www.getfreepdf.com/en/>
Do you have a copy at the moment ?
As I wrote in my cited post: I do not have access to Microsoft-< systems
and this will not be able to evaluate the program.
I can evaluate SoftMaker on different scales. Also, I do not use any PDF editing software other than PDFChain, pdftk and the LibTiff tools. For the time being, I consider the *necessity* to edit PDF *content* as evidence
of a faulty work flow.
On 2026-11-15 11:13, Michael Uplawski wrote:
Le Sat, 14 Nov 2026 04:30:36 -0500, Paul a |-crit-a:
On Sat, 11/14/2026 3:55 AM, Michael Uplawski wrote:
Free PDF Editor:
<https://www.getfreepdf.com/en/>
Do you have a copy at the moment ?
As I wrote in my cited post: I do not have access to Microsoft-< systems
and this will not be able to evaluate the program.
I can evaluate SoftMaker on different scales. Also, I do not use any PDF
editing software other than PDFChain, pdftk and the LibTiff tools. For the >> time being, I consider the *necessity* to edit PDF *content* as evidence
of a faulty work flow.
Me too.
Here's my problem... what word just means it's legitimately free for
non commercial personal use, and that's literally all that I care
about?
I consider the *necessity* to edit PDF *content* as evidence of a
faulty work flow.
On Sun, 11/15/2026 7:26 AM, Carlos E.R. wrote:
On 2026-11-15 11:13, Michael Uplawski wrote:
Le Sat, 14 Nov 2026 04:30:36 -0500, Paul a ocrita:
On Sat, 11/14/2026 3:55 AM, Michael Uplawski wrote:
Free PDF Editor:
<https://www.getfreepdf.com/en/>
Do you have a copy at the moment ?
As I wrote in my cited post: I do not have access to Microsoft systems
and this will not be able to evaluate the program.
I can evaluate SoftMaker on different scales. Also, I do not use any PDF >>> editing software other than PDFChain, pdftk and the LibTiff tools. For the >>> time being, I consider the *necessity* to edit PDF *content* as evidence >>> of a faulty work flow.
Me too.
If the text was handled as flows, I would think it would be
marginally feasible to edit a PDF.
But what I've seen of the "line at a time" editing idea,
that's mostly useless for any real purpose. The other issue
with such editing, is the "embedded subset fonts" are a curse.
You might not have the characters to edit a line. Over the years,
PDFs have degraded significantly, in terms of potential workflows.
You don't have ATMFM and Sans and Serif replacement fonts for
things like that.
On Sun, 15 Nov 2026 10:13:24 -0000 (UTC), Michael Uplawski wrote:
I consider the *necessity* to edit PDF *content* as evidence of a
faulty work flow.
Entirely fair comment.
Though the need to extract *information* from a PDF file can
arise sometimes.
And then I discovered that one scenario for this has already been
covered <https://ghostscript.readthedocs.io/en/latest/ZUGFeRD.html>
...
On Sat, 14 Nov 2026 12:57:57 -0400, Maria Sophia wrote:
Amazingly, it knew *instantly* a fake email address.
WTF? How?
I tried something random at hotmail.com, and it accepted that.
Lawrence DN++Oliveiro wrote:
On Sun, 15 Nov 2026 10:13:24 -0000 (UTC), Michael Uplawski wrote:
I consider the *necessity* to edit PDF *content* as evidence of a
faulty work flow.
Entirely fair comment.
Though the need to extract *information* from a PDF file can
arise sometimes.
And then I discovered that one scenario for this has already been
covered <https://ghostscript.readthedocs.io/en/latest/ZUGFeRD.html>
...
I must disagree. Vehemently so. But in a nice way. 'Cuz I don't disagree!
1. There is the ideal flow
2. And then, there is the real world
There should be no reason to refill printer ink or toner since the ideal
flow is to buy expensive refill inks and toner from the manufacturer, but
in the "real world" that I live in, there *is* a need to refill the tanks.
Same with PDFs. In an ideal world, you would never have any need to modify someone else's PDF, but I don't know anyone who lives in that ideal world.
Since Lawrence invested the energy to give us a hint in that URL, to edify others, since we always learn and teach at the same time, every moment of
our natural lives, Lawrence is pointing at ZUGFeRD, which is apparently a German standard for embedding structured invoice data inside a PDF, so that
a PDF is both a human-readable document and a machine-readable data file.
While Michael opines that needing to edit PDF content means our workflow is broken, Lawrence first agrees, then he makes a narrower point, which is
that sometimes we might not need to edit the PDF so much as needing to extract information from it. ZUGFeRD is the case where that problem has already been solved properly, at the format level, rather than by guessing.
Overall, most of what Michael and Lawrence are trying to teach us goes over my head, but I think we can summarize Michael's kind-hearted advice that editing PDFs is a sign of a bad workflow, just as needing to file an insurance claim is a sign of a bad driver, while Lawrence agrees, but also points out that reading data out of a PDF is sometimes unavoidable, where Lawrence suggests a fix, which is a format that carries the data alongside the presentation.
ZUGFeRD is the proof that this can be done right.
I never had to edit a PDF myself.
I agree with Michael that if there is a need to edit a PDF, the workflow
is wrong. You should have been supplied with the original document, not
the PDF.
If I had to, I recreated another original document of sorts.
Many years ago I had to correct a typo in a PDF, and that time I used Acrobat on Windows. I had the complete acrobat version supplied by my employer. I don't remember why I did not have access to the original document. That was the once time.
Given Einstein's book on special relativity was out of copyright (yes, it
has been a hundred years since we found that gravity is NOT a force), I
used Calibre to convert the PDF to an audio file that played on the iPad.
Carlos E.R. wrote:
I never had to edit a PDF myself.
I agree with Michael that if there is a need to edit a PDF, the workflow
is wrong. You should have been supplied with the original document, not
the PDF.
If I had to, I recreated another original document of sorts.
Many years ago I had to correct a typo in a PDF, and that time I used
Acrobat on Windows. I had the complete acrobat version supplied by my
employer. I don't remember why I did not have access to the original
document. That was the once time.
Hi Carlos,
Like I opined to the other experts, I both agree, and I disagree.
Thanks for explaining your use of fixing a typo in a PDF using the Adobe Acrobat payware, which I can't count the number of times I've done that.
So I *agree* with you that there are times when being able to munge a PDF
is a good thing, as I can't count the number of times I created a PDF of a web site (also using Adobe Acrobat payware) and then had to remove pages.
Often we have to re-order pages. We need to insert pages. Delete them.
There are "things" we need to do with PDFs when we don't have the original.
A simplistic view of the "real world" is that the real world doesn't exist.
I disagree.
As you know, I live in the "real world" of Android and iOS where, like it
or not, Windows, Linux and, yes, macOS also happen to exist in that world.
Some people, on the Android newsgroup, tell me there's 'something wrong'
that I use adb all day, every day, and my tactless answer, usually, to
them, is 'maybe you don't do anything on Android', which kind'a sort'a
would be my equally tactless response to anyone who claims that 'the
workflow is wrong' when you're just "trying to do something with PDF".
Now, I don't disagree if we *FULLY CONTROL THE ENTIRE WORKFLOW*, then, of course, we should save the original inputs to the PDF generation flow.
But, recently I had to spend a month in the compression chamber (as documented in the Windows newsgroup at the time) where they would provide "movies" but I wanted to have books read to me. Specific books.
Given Einstein's book on special relativity was out of copyright (yes, it
has been a hundred years since we found that gravity is NOT a force), I
used Calibre to convert the PDF to an audio file that played on the iPad.
But... and this is important... but the original conversion of the book had all sorts of "stuff" like equations and tables of contents and images with captions and a bibliography, etc., where I'm inside a 500-gallon propane
tank and the iPad is outside that tank under the control of the techs.
I can't ask the techs to skip that stuff, so I have to "do something" to
the PDF so that all that stuff is removed, and then it plays nicely.
There may be a better way to do that "stuff" in an ideal world, but what I resorted to was a way to edit the PDF that calibre spit out (although I
could have done it other ways, I had so many PDFs that did NOT need editing that I wanted to hone my workflow since I was in that chamber for a month).
A person who doesn't munge PDFs would just download existing audio books.
But is Einstein's theory of special relativity in a free audio book?
My point is that there are two kinds of people...--
a. People who don't do stuff
b. People who do stuff
If we "do stuff" then the "ideal workflow" will fail, and I will forever reference my Fort Meade days where we were doing stuff with someone else's data, where we had to figure out what that original data actually was.
In an ideal world, the Russians would have just given us their originals. But, my point about PDF munging, is we don't live in that ideal world.
I had tried fabricated gmail and protonmail addresses, but I did not
try one that I "thought" would be real, so I'm guessing they
actually sent an email and it bounced back in my case, but in yours,
it may have been real.
On Sun, 15 Nov 2026 16:04:26 -0400, Maria Sophia wrote:
I had tried fabricated gmail and protonmail addresses, but I did not
try one that I "thought" would be real, so I'm guessing they
actually sent an email and it bounced back in my case, but in yours,
it may have been real.
It could be they initiate an SMTP connection, get as far as the rCLRCPT
TOrCY exchange, and get back a response that either says to proceed
(address is valid) or not (address is invalid).
| Sysop: | Amessyroom |
|---|---|
| Location: | Fayetteville, NC |
| Users: | 76 |
| Nodes: | 6 (0 / 6) |
| Uptime: | 54:24:00 |
| Calls: | 1,265 |
| Calls today: | 1 |
| Files: | 1,362 |
| D/L today: |
3 files (2,684K bytes) |
| Messages: | 285,563 |